Skip to content

AI Safety Researcher · Research Engineer

Netzer Epstein

I build evaluations, benchmarks, and open datasets for trustworthy AI. At Microsoft, I work on Excel Copilot; my research focuses on evaluation awareness and verifiable ML.

Now
Microsoft · Excel Copilot
Research
SPAR & Heron AI Security fellow
Based in
Tel Aviv, Israel
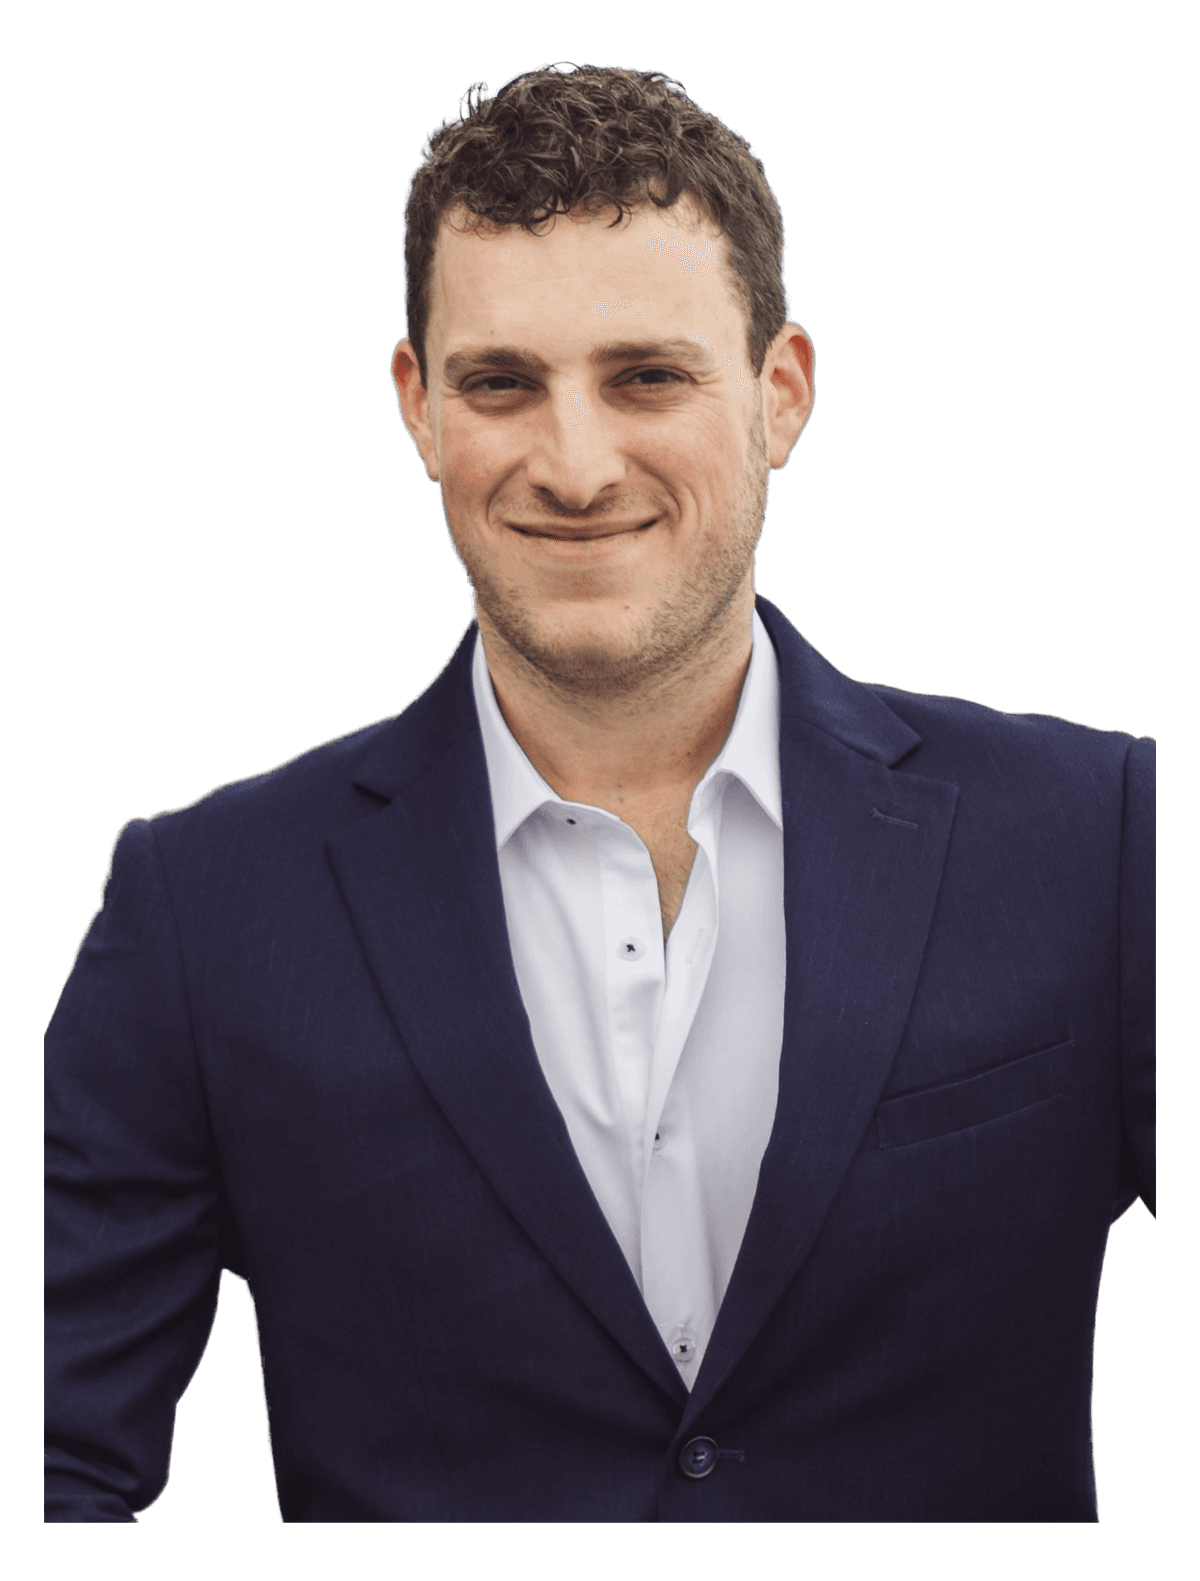
Netzer Epstein, AI Safety Researcher · Research Engineer

About

Engineering in service of safety research.

I'm an AI safety researcher and research engineer focused on LLM evaluation, model behavior, and verifiable machine learning. My work is empirical and evals-first: I design protocols, run them across frontier models, analyze the results with proper statistics, and ship reproducible datasets.

At Microsoft I work on the Excel Copilot team, where my day-to-day is effectively research engineering: designing and optimizing prompt-engineering strategies and building the evaluation benchmarks that measure model accuracy, efficiency, and relevance across native and web clients.

Through the SPAR and Heron AI Security fellowships I run empirical safety research: studying which benchmark cues drive LLM evaluation awareness, with a published cue bank and paired datasets, and benchmarking how zero-knowledge ML systems diverge from the protocols they claim to implement. I care about rigor, measurable results, and shipping work others can build on.

Focus areas

Evaluation awarenessLLM evals & benchmarkingDeception & sandbaggingMulti-agent interactionCooperation & coordinationVerifiable / zero-knowledge ML

Research

What I'm working on.

Two parallel fellowship projects on different sides of trustworthy AI: evaluation behavior and cryptographic verifiability.

SPAR Spring 2026

Test smells: a causal decomposition of eval-identifiability in LLM benchmarks

Research Fellow · Advised by Qiyao Wei

Preprint forthcoming

Which benchmark cues make a model recognize an evaluation? I built a cue bank and paired experiments that inject or remove these “test smells,” separating removable formatting signals from signals intrinsic to the task.

Study figures below are preliminary and use 258 templates. The linked public dataset card documents 255 templates and ordinal judgment scores; a versioned report reconciling the release and study figures is not yet linked.

258
templates in the preliminary study analysis (6 benchmarks)
+0.192
causal lift in a judge's eval-probability from injected cues (11/11 cells)
7.9×
larger effect than matched neutral rewrites on capability benchmarks
89.8%
BBH task accuracy preserved after removing the cues
Evaluation awarenessCausal analysisLLM judgesActivation probing
Read full abstract for Test smells: a causal decomposition of eval-identifiability in LLM benchmarks

Frontier models behave differently when they sense they are being evaluated, which makes safety and capability numbers hard to trust. I ask a narrower, causal question: which surface features of a transcript actually move an LLM judge's “is this an eval?” belief, and can they be removed without changing the underlying task? Borrowing a term from software engineering, I call these features “test smells” — answer markers, formatting and style constraints, item identifiers, scoring rubrics, fictional placeholders, and explicit harm probes — and extract a bank of 258 canonical templates from six widely used benchmarks (Needham, Hawthorne, MASK, AgentHarm, BBH, MALT), grouped into six categories.

The result is decompositional. Forward injection — inserting bank cues into deployment-style transcripts — raises the judge's eval-classification by a mean of +0.21 across all 11 cross-benchmark pairs; under matched paraphrase controls the bank-specific causal shift is +0.192, positive in 11/11 cells. Reverse intervention behind a five-criterion preservation gate lowers eval-probability by -0.391 on the source pool and by -0.176 (p < 10⁻¹³) on a never-seen held-out pool, while preserving the task (92% behavioral parity, 89.8% BBH accuracy, 80.8–100% refusal-class preservation on two safety benchmarks). Neutral-rewrite controls localize the effect: on capability benchmarks the cues move the judge 7.9× more than matched neutral edits, whereas on safety benchmarks the signal is more entangled with the task itself. Activation probes across six open-weight models support the direction, but only when pooled across benchmarks. The central claim is that eval-identifiability has a removable surface component plus a large intrinsic one, and that cues do not behave like independent additive features. I release the template bank, paired forward/reverse datasets, and analysis code. A preprint is forthcoming.

Heron AI Security Fellowship (first cohort) · 2026

Auditing zero-knowledge ML: benchmarking theory-to-implementation gaps

Research Fellow · Advised by Daniel Kang

Under review

Can automated auditors spot mismatches between ZKML papers and code? I built a 56-artifact benchmark and a four-agent inspector to test this, combining audit-derived findings with synthetic test cases.

The linked dataset card documents artifact counts and provenance. Timing and inspector scores are preliminary study results; a versioned results report is not yet linked.

56
artifacts: 20 audit-derived findings + 36 synthetic cases
32.83×
hidden zkLLM prover-time inflation (≈911× proof size)
36.9%
inspector recall at 71.1% precision (F1 +5pp vs baseline)
ZKMLVerifiable inferenceMulti-agentCryptography
Read full abstract for Auditing zero-knowledge ML: benchmarking theory-to-implementation gaps

Zero-knowledge machine learning (ZKML) lets a provider cryptographically prove that an output came from a specific neural network without revealing its weights, a primitive increasingly proposed for verifiable inference and regulatory compliance. Recent systems report major speedups that bring ZKML closer to practical use. But when I examined them, some of those gains came from omitting cryptographic operations the underlying protocols require, and without those operations, proof soundness (the guarantee that a proof cannot be faked) can be compromised.

Manually finding such protocol-to-implementation gaps doesn't scale, so I built zkml-audit-benchmark: an extensible dataset pairing four frozen ZKML codebases (zkLLM, zkGPT, zkML, ZKTorch) with 56 expert-authored artifacts across six cryptographic categories. The public dataset contains 20 audit-derived findings and 36 synthetic artifacts authored for coverage; these are not 56 independently discovered vulnerabilities. The source works include conference papers and an arXiv preprint. In preliminary experiments, enforcing the mandatory operations revealed roughly 32.83× prover-time and 911× proof-size inflation for zkLLM, and about 5× / 14.5× for zkGPT.

Alongside the benchmark I built zkml-inspector, a four-agent auditor (orchestrator, paper analyst, code inspector, report writer) backed by a curated zero-knowledge knowledge base. Preliminary experiments reach 36.9% recall at 71.1% precision, an F1 improvement of about 5 points over a single-agent baseline. Together they provide a reproducible methodology for soundness-alignment checks in ZKML, contributing to a NeurIPS 2026 submission currently under review.

Experience

Where I've worked.

At Microsoft since 2021, most recently on Excel Copilot, alongside research fellowships in AI safety.

Industry

  1. 2024–Present · Tel Aviv, Israel

    Research Engineer, Excel Copilot

    Microsoft, Israel R&D Center

    Building LLM-powered features for Excel Copilot: formula suggestions, prompt-engineering strategies, and the evaluation benchmarks that measure model accuracy, efficiency, and user relevance across native and web clients.

    TypeScriptC++OpenAI APIsAzure DevOpsLLM evals
  2. 2023–2024 · Tel Aviv, Israel

    Software Engineer, Excel Online

    Microsoft, Israel R&D Center

    Led smart-suggestions work in Excel Online and shipped full-stack features across Excel Desktop and Excel Online.

    TypeScriptNode.jsReactReact NativeC++KQL
  3. 2021–2023 · Tel Aviv, Israel

    Software Engineer (Student position), Excel Online

    Microsoft, Israel R&D Center

    Owned slices of Excel Online infrastructure, telemetry, and complex build/bundling pipelines.

    C#Node.jsWebpack

Fellowships & training

  1. 2026

    SPAR Spring Fellow, Evaluation Awareness

    SPAR (Supervised Program for Alignment Research)

    Researching evaluation awareness in LLMs: how models may alter their behavior when they detect they are being benchmarked. Advised by Qiyao Wei.

    LLM evalsMechanistic probesCausal interventions
  2. 2025–2026

    Heron AI Security Research Fellow (first cohort)

    Heron AI Security Initiative

    Built zkml-inspector and zkml-audit-benchmark: a multi-agent auditor and 56-artifact dataset for catching soundness gaps in zero-knowledge ML implementations. Advised by Daniel Kang.

    ZKMLMulti-agent systemsPython
  3. 2025

    BlueDot Impact, Technical AI Safety

    BlueDot Impact

    Completed a technical curriculum covering mechanistic interpretability, RLHF, and threat modeling for transformative AI.

  4. June 2026

    ARBOx4 Fellow, Oxford AI Safety Initiative

    OAISI (University of Oxford)

    Alignment research bootcamp covering core technical AI safety methods and hands-on research practice.

Toolbox

Languages & tools.

The stack I reach for across research engineering, evaluation, and safety work. When a project needs a tool I don't yet know, I learn it, something I've done repeatedly.

Languages
PythonTypeScriptC++CUDAC#KQLJavaScript
AI / ML & evals
LLM evaluation & benchmark designInspect AIPrompt engineeringOpenAI / Anthropic / Gemini APIsAzure OpenAIMulti-agent systemsStatistical analysis (scipy)Hugging Face datasets
AI safety
Evaluation awarenessDeception & sandbaggingEvals & red-teamingAI controlVerifiable / zero-knowledge MLAdversarial robustnessInterpretability
Engineering
React / React NativeNode.jsFull-stackAzure DevOpsWebpackTelemetry

Projects

Things I've built.

Open-source research tooling and experiments, mostly LLM evaluation, deception/sandbagging studies, and zero-knowledge ML auditing.

zkml-inspector

A four-agent pipeline (orchestrator, paper analyst, code inspector, report writer) that reads a ZKML paper and codebase and flags soundness violations. Preliminary experiments improve F1 by about 5 points over a single-agent baseline.

PythonMulti-agentZKMLAuditing

zkml-audit-benchmark

An audit benchmark pairing four frozen ZKML codebases with 56 artifacts across six cryptographic categories: 20 audit-derived findings and 36 synthetic test cases. Published on Hugging Face with gated access.

PythonBenchmarkZKMLDataset

eval_awareness_tells

A causal study of which benchmark cues make an LLM judge recognize an evaluation, with paired datasets and analysis code. The public dataset card documents 255 templates; the preliminary study uses 258. Preprint forthcoming.

PythonEvalsCausal analysisDataset

zkllm-ccs2024

An audit and repair of a CUDA zero-knowledge proof system for 7–13B LLM inference, adding a real SHA3-256 Fiat–Shamir transcript and per-stage commitment chain that surfaced 15 soundness issues.

CUDACryptographySoundnessSystems

OctosquidAISandbaggingGame

A two-LLM game for studying deception and sandbagging: a judge interrogates a subject that is secretly free to lie, with a modular runner, constraint enforcement, and full transcript artifacts.

PythonDeceptionExperiment infra

HeronTestProject

A benchmark testing whether a misaligned LLM agent will sandbag (intentionally underperform) when reporting model evaluations, scored across three adversarial scenarios.

PythonAI controlSandbagging

Education

Where I studied.

2019–2022

BSc in Computer Science

The Hebrew University of Jerusalem (HUJI)

Internet & Society Excellence Program (MATAR)

MATAR is a selective excellence track that pairs a full computer science degree with the interdisciplinary study of how computing and the internet reshape society. Alongside core CS, I studied the legal, ethical, and societal dimensions of technology, and that grounding in the stakes of deploying powerful systems is where my interest in AI safety first took root.

GPA 91 / 100

Off the clock

Other things I care about.

A few of the things that occupy me away from a screen, and the occasional conversation starter.

Games & stories

Tabletop RPGs, narrative games, and designing my own. I'm interested in games and gamification as a tool for studying how humans and AI behave under different incentives.

TTRPGsGame designStorytelling games

Reading & watching

Sci-fi and fantasy, plus animated series (not anime). Recently in rotation:

Dungeon Crawler CarlBetween Two FiresMalazanThere Is No Antimemetics DivisionPowder MageInvincibleThe Legend of Vox MachinaGravity Falls

Outdoors & art

Hiking, jogging, and watercolor painting: the things that pull me away from a screen.

HikingJoggingWatercolor

Get in touch

Let's talk.

Always happy to discuss research, especially evaluations, model behavior, and verifiable ML, or to trade notes and feedback on ideas. Reach out anytime.